A patch management policy is the formal document that defines who patches what, how fast, and under what authority. It exists to turn vulnerability remediation from an ad hoc scramble into a repeatable process auditors can verify. If you don’t have one yet, the fastest path forward is to adapt a proven template and assign a named policy owner today.
TL;DR:
- A formal patch management policy defines clear roles, responsibilities, and timelines, which improve auditability and enforceability across the organization.
- Asset inventory must include hostname, OS version, business owner, criticality, and patch status to prevent scope gaps and compliance failures.
- Remediation SLAs should be based on CVSS scores and exploitation status, with explicit procedures for adjusting timelines during business-critical periods.
- Automated discovery, deployment, and reporting tools are essential for tracking compliance, enforcing SLAs, and supporting audit evidence at scale.
- Separate policy from tool instructions, keep roles and responsibilities tied to job titles, and document exceptions with expiration dates to maintain a defensible remediation process.
Table of Contents
- Why Your Organization Needs a Formal Patch Management Policy
- What a Patch Management Policy Should Cover: Purpose, Scope, and Definitions
- Roles, Responsibilities, and Accountability: Who Does What
- Classification, Prioritization, and SLAs: Sample Remediation Timelines
- Asset Inventory, Maintenance Groups, and Scope Enforcement
- Testing, Staged Rollouts, Verification, and Remediation Tracking
- Exception Handling and Risk Acceptance Process
- Reporting, Audit Evidence, and Compliance Mapping
- Implementation Checklist: 5 Steps to Adopt a Patch Management Policy
- Policy Template: Reusable Headings, Required Fields, and Fill-in Examples
- How Mavericks Office Solutions Helps Teams Operationalize Patch Policies
- Author’s Practitioner Notes: Common Pitfalls and Pragmatic Fixes
- How a Managed IT Partner Can Accelerate Policy Adoption
- Sources
Why Your Organization Needs a Formal Patch Management Policy
Without a written policy, patching happens whenever someone remembers, and that inconsistency is exactly what auditors and attackers both notice. NIST SP 800-40r4 describes an enterprise patch management policy as the formal governing document that defines roles, responsibilities, and remediation timelines, and it serves as the baseline examiners expect to see during a compliance review.
A written policy gives you three things a verbal understanding never will:
- Audit evidence. PCI DSS, SOC 2, and ISO 27001 assessors all ask for a documented process, not a description of good intentions.
- Repeatability. Patching stops depending on which technician is on shift and starts following the same rules every time.
- Enforceability. You can hold a maintenance group accountable to an SLA only if that SLA exists in writing somewhere leadership signed off on.
That last point matters more than it sounds. Getting executive sign off before you need a maintenance window, not during an active exploit, is what makes it possible to actually take production systems offline when a critical patch demands it. Leadership buy in secured in advance removes the friction that otherwise kills timely remediation.
What a Patch Management Policy Should Cover: Purpose, Scope, and Definitions
Before you write a single SLA, define what the policy actually governs. Scope creep, or the opposite problem of gaps nobody notices until a breach, both trace back to a fuzzy scope section.
Your scope should enumerate every asset category the policy touches:
- Servers (physical and virtual), on premises and cloud
- Endpoints: desktops, laptops, and mobile devices
- Network devices: firewalls, switches, routers, and wireless controllers
- Applications and firmware, including third-party software and IoT devices
- A rule for how new assets enter scope automatically (tied to provisioning, not a manual add-on step)
That last bullet solves one of the most common audit findings: a server stood up six months ago that nobody ever added to the patching cycle because onboarding and security scope lived in separate spreadsheets.
Definitions deserve their own section, even though they feel like paperwork. Terms like CVSS (Common Vulnerability Scoring System, the 0 to 10 severity score), KEV (CISA’s Known Exploited Vulnerabilities catalog), maintenance group (a set of assets patched together on the same schedule), and exception (a documented, time bound deviation from SLA) need consistent meaning across every team that touches the policy. Without shared definitions, one team’s “critical” is another team’s “high,” and SLA reporting turns into a translation exercise.
Finally, be explicit about what the policy is not. It sets governance, roles, and timelines. It should never contain step by step tool instructions, specific command syntax, or vendor screenshots. That detail belongs in a separate SOP or runbook, referenced by name but kept out of the policy body so a tool change doesn’t force a full policy reapproval.
Roles, Responsibilities, and Accountability: Who Does What
A policy without named owners is a wish list. Every effective program assigns a single patch owner role per system type and ties approval authority to specific job titles, not to “IT” as an abstraction.
At minimum, your policy needs to name:
- Policy owner: the individual (often a CISO, IT director, or security officer) accountable for the document itself, its annual review, and its accuracy.
- Asset owners: the team or role responsible for a given maintenance group’s patch compliance, inventory accuracy, and SLA adherence.
- Change approver: who signs off on standard maintenance windows versus who has authority to approve an emergency, out of cycle patch.
- Escalation path: what happens when a critical patch can’t be applied within SLA, and who gets notified at each stage of delay.
The RACI model (Responsible, Accountable, Consulted, Informed) works well here because it forces you to separate “who does the work” from “who owns the outcome.” A system administrator might be Responsible for deploying a patch, but the asset owner stays Accountable for whether that system hits its SLA.
Tie every role to something measurable. Inventory accuracy above a set threshold, SLA compliance percentage, or exception count per quarter all give you a way to know whether ownership is working or just written down. A privileged access management framework often runs in parallel here, since the accounts used to push automated patches need the same tight ownership controls as the patching process itself.
Classification, Prioritization, and SLAs: Sample Remediation Timelines
SLAs are the part auditors read first, and vague ones are the fastest way to fail a review. Base severity tiers on CVSS score combined with exploitation status, then set a remediation clock for each tier.
A workable structure looks like this:
| Severity tier | Criteria | Sample SLA |
|---|---|---|
| Emergency | Actively exploited (on CISA’s KEV catalog) | Within a few days |
| Critical | CVSS 9.0-10.0, no known exploit yet | Within about a week |
| High | CVSS 7 to 8 | Within a few weeks |
| Medium | CVSS 4 to 6 | Within up to several months |
| Low | CVSS under 4 | Next scheduled cycle |
Pro Tip: Don’t copy generic SLA ranges without adjusting for asset criticality. A medium severity vulnerability on a domain controller deserves a shorter clock than a critical one on an isolated test machine. Industry guidance frames these ranges, including a common benchmark of remediating critical vulnerabilities within roughly 72 hours, as starting points to adapt to your own risk tolerance, not fixed rules.
Business constraints are real, and your policy should say so explicitly. A retailer can’t take point of sale systems down during the holiday shopping season no matter what the SLA clock says, so build in a documented process for temporarily adjusting timelines under defined conditions rather than letting the SLA get quietly ignored.
None of this scales on spreadsheets. Manual tracking works for a dozen endpoints; it collapses at a few hundred, which is exactly why nearly every serious patch management program leans on automated discovery, deployment, and reporting tools to enforce SLAs instead of hoping someone remembers.
Asset Inventory, Maintenance Groups, and Scope Enforcement
You cannot patch what you cannot see, and an incomplete inventory is the single most common root cause behind missed remediation deadlines. Your policy should specify the minimum fields every asset record must carry:
- Hostname and unique identifier, so the same device isn’t tracked under two different names by two different tools.
- Operating system and version, since patch availability and end of life dates depend entirely on this.
- Business owner, the person or team accountable if this asset misses its SLA.
- Criticality rating, tying the asset to a maintenance group and, by extension, an SLA tier.
- Current patch level and last scan date, the fields your compliance percentage is actually calculated from.
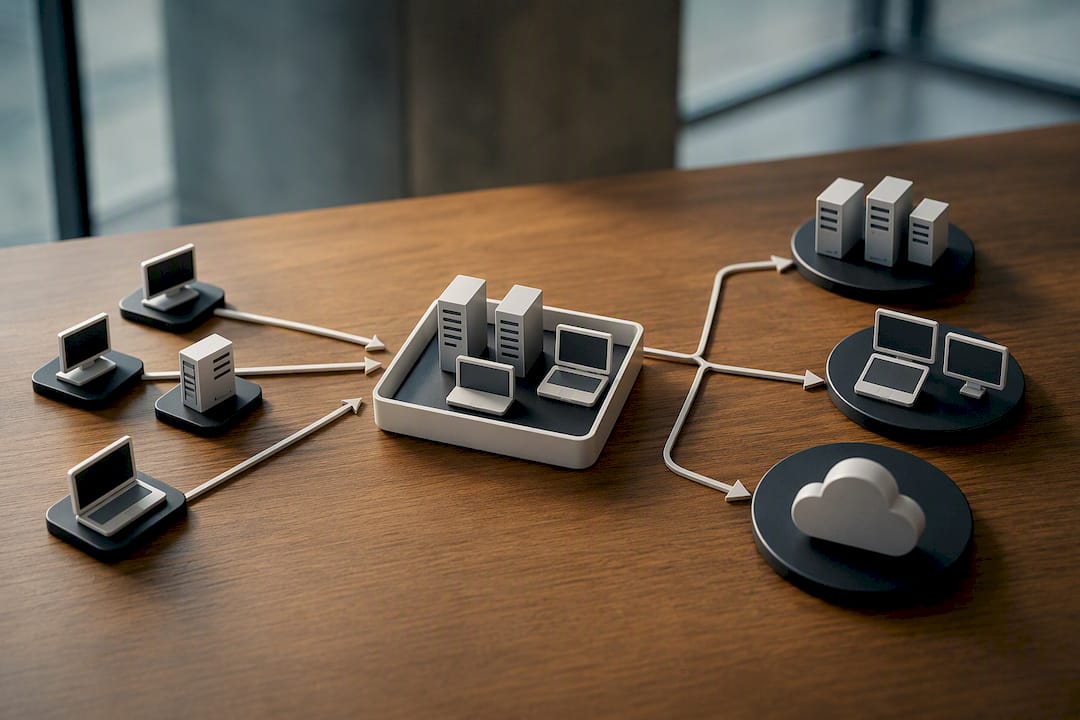
Maintenance groups organize assets that share a deployment schedule, whether that’s grouped by criticality, department, or operating system family. CISA’s vulnerability management guidance recommends assigning maintenance groups explicitly and using phased deployment patterns within them rather than pushing every patch to every system simultaneously.
The rule that closes the biggest gap: newly provisioned assets must enter the inventory and get assigned to a maintenance group as part of the provisioning workflow itself, not as a follow-up task. A server that exists for three weeks before anyone adds it to the patch cycle is a server that’s been unpatched for three weeks by policy, not by accident.
Testing, Staged Rollouts, Verification, and Remediation Tracking
Pushing a patch to every production system at once is how a single bad update becomes a company-wide outage. CISA’s guidance recommends phased deployment, often described as a canary approach: patch a small, low risk subset first, watch for problems, then expand to the broader maintenance group once the canary batch proves stable.
A defensible rollout process includes:
- A canary group representative of your broader environment, not just the least important machines you own.
- A defined observation window (24 to 48 hours is common) before expanding the rollout.
- A documented rollback plan for every deployment, tested before it’s needed, not during an incident.
- Verification metrics captured automatically: percent compliant per maintenance group, reboot status, and failed deployment count.
Pro Tip: A patch that “deployed successfully” and a patch that “actually installed and the system rebooted into the patched state” are two different facts. Confirm the second one, not just the first, before marking a vulnerability closed.
Track every open vulnerability through a repository from discovery to closure. CISA frames this as a remediation lifecycle: identify, assign, remediate, verify, close, with a timestamp at each stage. That repository is also what turns your compliance percentage from a guess into a number you can defend to an auditor, because you can show exactly when each vulnerability moved from open to closed.
Exception Handling and Risk Acceptance Process
Some systems can’t be patched on schedule. A legacy application that breaks on the newest update, a vendor certification that hasn’t caught up to the latest firmware, or a maintenance window that legitimately can’t happen this quarter are all real scenarios your policy needs to accommodate without creating a permanent loophole.
A defensible exception process requires:
- Named approval authority. Exceptions get approved by a specific role (often the policy owner or a security committee), never self-approved by the team responsible for the missed SLA.
- Written justification. Why the patch can’t be applied, and what the business impact of forcing it would be.
- Compensating controls. Network segmentation, additional monitoring, or restricted access that reduces risk while the vulnerability stays open.
- Mandatory expiration date. No exception is permanent. Every one gets a review date, and the default outcome at that date is remediation, not automatic renewal.
Effective programs treat every exception as a timeboxed mitigation, not a policy carve out. That distinction, expiration by default rather than indefinite tolerance, is what separates a defensible risk acceptance process from a graveyard of vulnerabilities nobody ever revisits. Log every exception in the same repository that tracks your remediation lifecycle, so auditors see the full picture: what’s open, what’s excepted, and why.
Reporting, Audit Evidence, and Compliance Mapping
Reporting serves two different audiences, and conflating them is a common mistake. Operational reports (weekly or biweekly) go to IT teams and track patch compliance percentage, failed deployments, and open exceptions by maintenance group. Executive reports (monthly or quarterly) roll that up into mean time to remediate (MTTR) by severity tier and overall percent compliant, framed as risk rather than tickets.
The evidence auditors actually want should generate automatically from your tooling, not from someone building a slide deck the night before a review. That means your patch management platform needs to export compliance percentage, timestamped remediation records, and exception logs on demand.
Map your policy language directly to the frameworks you’re assessed against:
- NIST SP 800-40: cite it as the baseline for your policy’s structure and remediation timelines, since NIST SP 800-40 functions as the defensible baseline auditors expect.
- PCI DSS: critical vulnerabilities on cardholder data environment systems need explicit remediation timelines in your policy text, not just implied urgency.
- ISO 27001: reference your patching process under vulnerability management controls, with evidence of the review cadence.
- SOC 2: tie remediation SLAs to the security and availability trust criteria, since that’s usually where an assessor looks first.
Implementation Checklist: 5 Steps to Adopt a Patch Management Policy
Adopting a policy doesn’t require starting from a blank page, and it shouldn’t take a full quarter to get a working draft in front of stakeholders. Sequence the work this way:
- Assign a policy owner in week one. Nothing else on this list moves forward without a named individual accountable for it.
- Build or validate your asset inventory within 30 days, since every SLA and maintenance group depends on knowing what you actually have.
- Set SLA tiers by severity and asset criticality, then get them signed off by leadership before you need to enforce them under pressure.
- Automate discovery, deployment, and reporting, and pilot the process on one maintenance group before rolling it out company wide, targeting the 60 day mark.
- Publish the policy and train stakeholders by day 90, including a short session for non-IT leadership on why maintenance windows matter.
Two things you can do this week, before the full rollout, that immediately reduce audit exposure: name the policy owner in writing, and pull a current inventory export so you know your actual starting compliance percentage. Both take a few hours and give you a defensible answer the next time someone asks “do we have a patch policy.”
Policy Template: Reusable Headings, Required Fields, and Fill-in Examples
A policy document that follows a consistent structure is easier for auditors to review and easier for your team to maintain. Use this table of contents as your starting skeleton:
- 1. Purpose: one paragraph stating the policy exists to reduce risk from unpatched vulnerabilities and satisfy compliance obligations.
- 2. Scope: list of asset categories covered, plus the rule for how new assets enter scope.
- 3. Definitions: CVSS, KEV, maintenance group, exception, and any internal terms specific to your environment.
- 4. Roles and responsibilities: policy owner, asset owners, change approver, escalation path, in a RACI table.
- 5. Classification and SLAs: severity tiers and remediation timelines, matching your risk tolerance.
- 6. Testing and deployment: canary requirements, phased rollout rules, rollback expectations (kept high level; detailed steps live in your SOP).
- 7. Exception handling: approval authority, required documentation, expiration rules.
- 8. Reporting: what gets reported, to whom, and how often.
- 9. Compliance mapping: which frameworks this policy satisfies and how.
- 10. Review cadence: how often the policy itself gets revisited (annually, at minimum).
Keep every section at the level of “what” and “who.” The “how,” specific commands, tool configurations, screenshots, belongs in a separate SOP referenced by name in section 6. That separation is what saves you from a full reapproval cycle every time you switch patching tools. Adapt each heading into your organization’s own phrasing and approval workflow before circulating it for sign off.
How Mavericks Office Solutions Helps Teams Operationalize Patch Policies
Writing the policy is half the work. Operating it, week after week, across every endpoint and server you own, is where most internal teams run out of bandwidth. Managed patching paired with 24/7 monitoring covers exactly the gap that turns a well written policy into an enforced one: continuous scanning, scheduled deployment by maintenance group, and documented evidence for every remediation cycle.
If you’re evaluating a managed partner against your own policy, ask three questions directly: Does their reporting map to your SLA tiers, or will you have to translate their format into yours? Who answers when a patch fails at 2 a.m., and how fast? A provider with a local, USA-based help desk and fast response time delivers the kind of response speed a policy’s emergency SLA tier depends on.
Author’s Practitioner Notes: Common Pitfalls and Pragmatic Fixes
The policies that fail an audit almost always made the same mistake: they tried to be a runbook and a governance document at once. Keep the policy focused on scope, roles, SLAs, and exceptions. Push tool-specific commands and configuration steps into a separate SOP, so a tool migration next year doesn’t force a full reapproval.
Name owners by job title, not by department, and put a hard expiration date on every exception before you approve it. Automate your evidence collection from day one. Manually reconstructing six months of remediation history for an auditor is a miserable way to spend a week, and it’s entirely avoidable.
— Jeffrey
How a Managed IT Partner Can Accelerate Policy Adoption
Mavericks Office Solutions is a direct route to putting this policy into daily operation without hiring a dedicated patch team. Our managed IT services cover the parts of the checklist above that eat the most internal time: continuous asset inventory, automated deployment by maintenance group, and audit-ready reporting mapped to your SLA tiers.

When you evaluate any vendor for this role, ask for proof of SLA alignment, sample reporting output, and confirmation of who answers support calls. A provider with a local, USA-based help desk instead of an offshore call center, with a fast average response time, is important when a critical patch window depends on someone actually picking up the phone. For businesses that also need PCI-aligned controls, our PCI compliance guide is a useful companion read while you scope the engagement.
If your policy exists on paper but not in practice, contact Mavericks Office Solutions to schedule a managed IT consultation and find out what it takes to get your patch program fully operational.
Sources
Two references belong in the citation list of any policy you publish. NIST SP 800-40r4 provides the federal baseline for patch management planning, covering roles, prioritization, and testing guidance that most compliance frameworks reference indirectly. CISA’s Vulnerability Management Resource Guide adds practical detail on maintenance groups, phased deployment, and remediation tracking that NIST covers at a higher level.
Citing both by name in your policy document, rather than paraphrasing them without attribution, gives auditors a direct line back to the standards your remediation timelines and role structure are built on.
- Guide to Enterprise Patch Management Planning: Preventive Maintenance for Technology (NIST SP 800-40r4)
- Vulnerability Management Resource Guide (CISA)
- Patch management policy: why you need it, how to implement it and best practices | ManageEngine